Qwen4 Max Review: Benchmarks, Pricing, and When to Upgrade

By Nathan Cole
MyClaw Editorial
MyClaw
Run Best-in-Class AI Agents Now
Run OpenClaw or Hermes Agent on managed MyClaw hosting, so your AI agent stays online, updated, and ready for real work.
AI Takeaway
- Is Qwen4 Max available now? Yes. Alibaba released the full model on November 16, 2026. The API model IDs are
qwen4-maxon QwenCloud andqwen/qwen4-maxon OpenRouter. - What improved over Qwen3.8 Max? Alibaba reports about 60% lower average task cost on its Work360 benchmark. In Artificial Analysis’s independent evaluation, Qwen4 Max scored 43 on the Intelligence Index, up from 34 for Qwen3.8 Max (0902).
- How much does the API cost? On QwenCloud’s Singapore endpoint, uncached input costs $1.50 per million tokens and output costs $4.50 per million. Both rates are 25% lower than the listed Qwen3.8 Max rates.
- Should you upgrade? Try Qwen4 Max on a multi-file code change, a document review that draws on several sources, or a job with multiple tool calls. Switch the workflow if the model passes more often at the same spend or saves enough review time to justify its cost.
What Qwen4 Max Is and What Changed After the Preview
Qwen4 Max is Alibaba’s hosted flagship for reasoning, coding, and work with visual inputs. Alibaba introduced Qwen4 Max Preview on November 11 under the Token Plan. The full release came five days later with pay-as-you-go API access. If your integration still calls qwen4-max-preview, update the model ID in a test run and check that the full model handles the inputs and tools your job needs.
| Capability | Qwen4 Max |
|---|---|
| Advertised context window | 1 million tokens |
| Inputs | Text, images, and video |
| Output | Text |
| QwenCloud Chat Completions output cap | 131,072 tokens with thinking off. Up to 262,144 with thinking on, shared between reasoning and the answer. |
| API features | Function calling and structured outputs. Check which features your client and provider expose. |
Both Max generations advertise a one-million-token context window. If you already use Qwen3.8 Max for long requests, test whether Qwen4 Max finds and uses the right details in the same material. When sizing a request, leave room for the answer, reasoning tokens, and any tool results the conversation accumulates.
Alibaba has announced plans to release weights for smaller Qwen4 models. If you need to run a model locally today, Qwen 3.8 Flash-Next vs. Qwen 3.8 27B compares two open-weight options and their memory requirements.
Qwen4 Max Benchmarks and How They Compare With Qwen3.8 Max
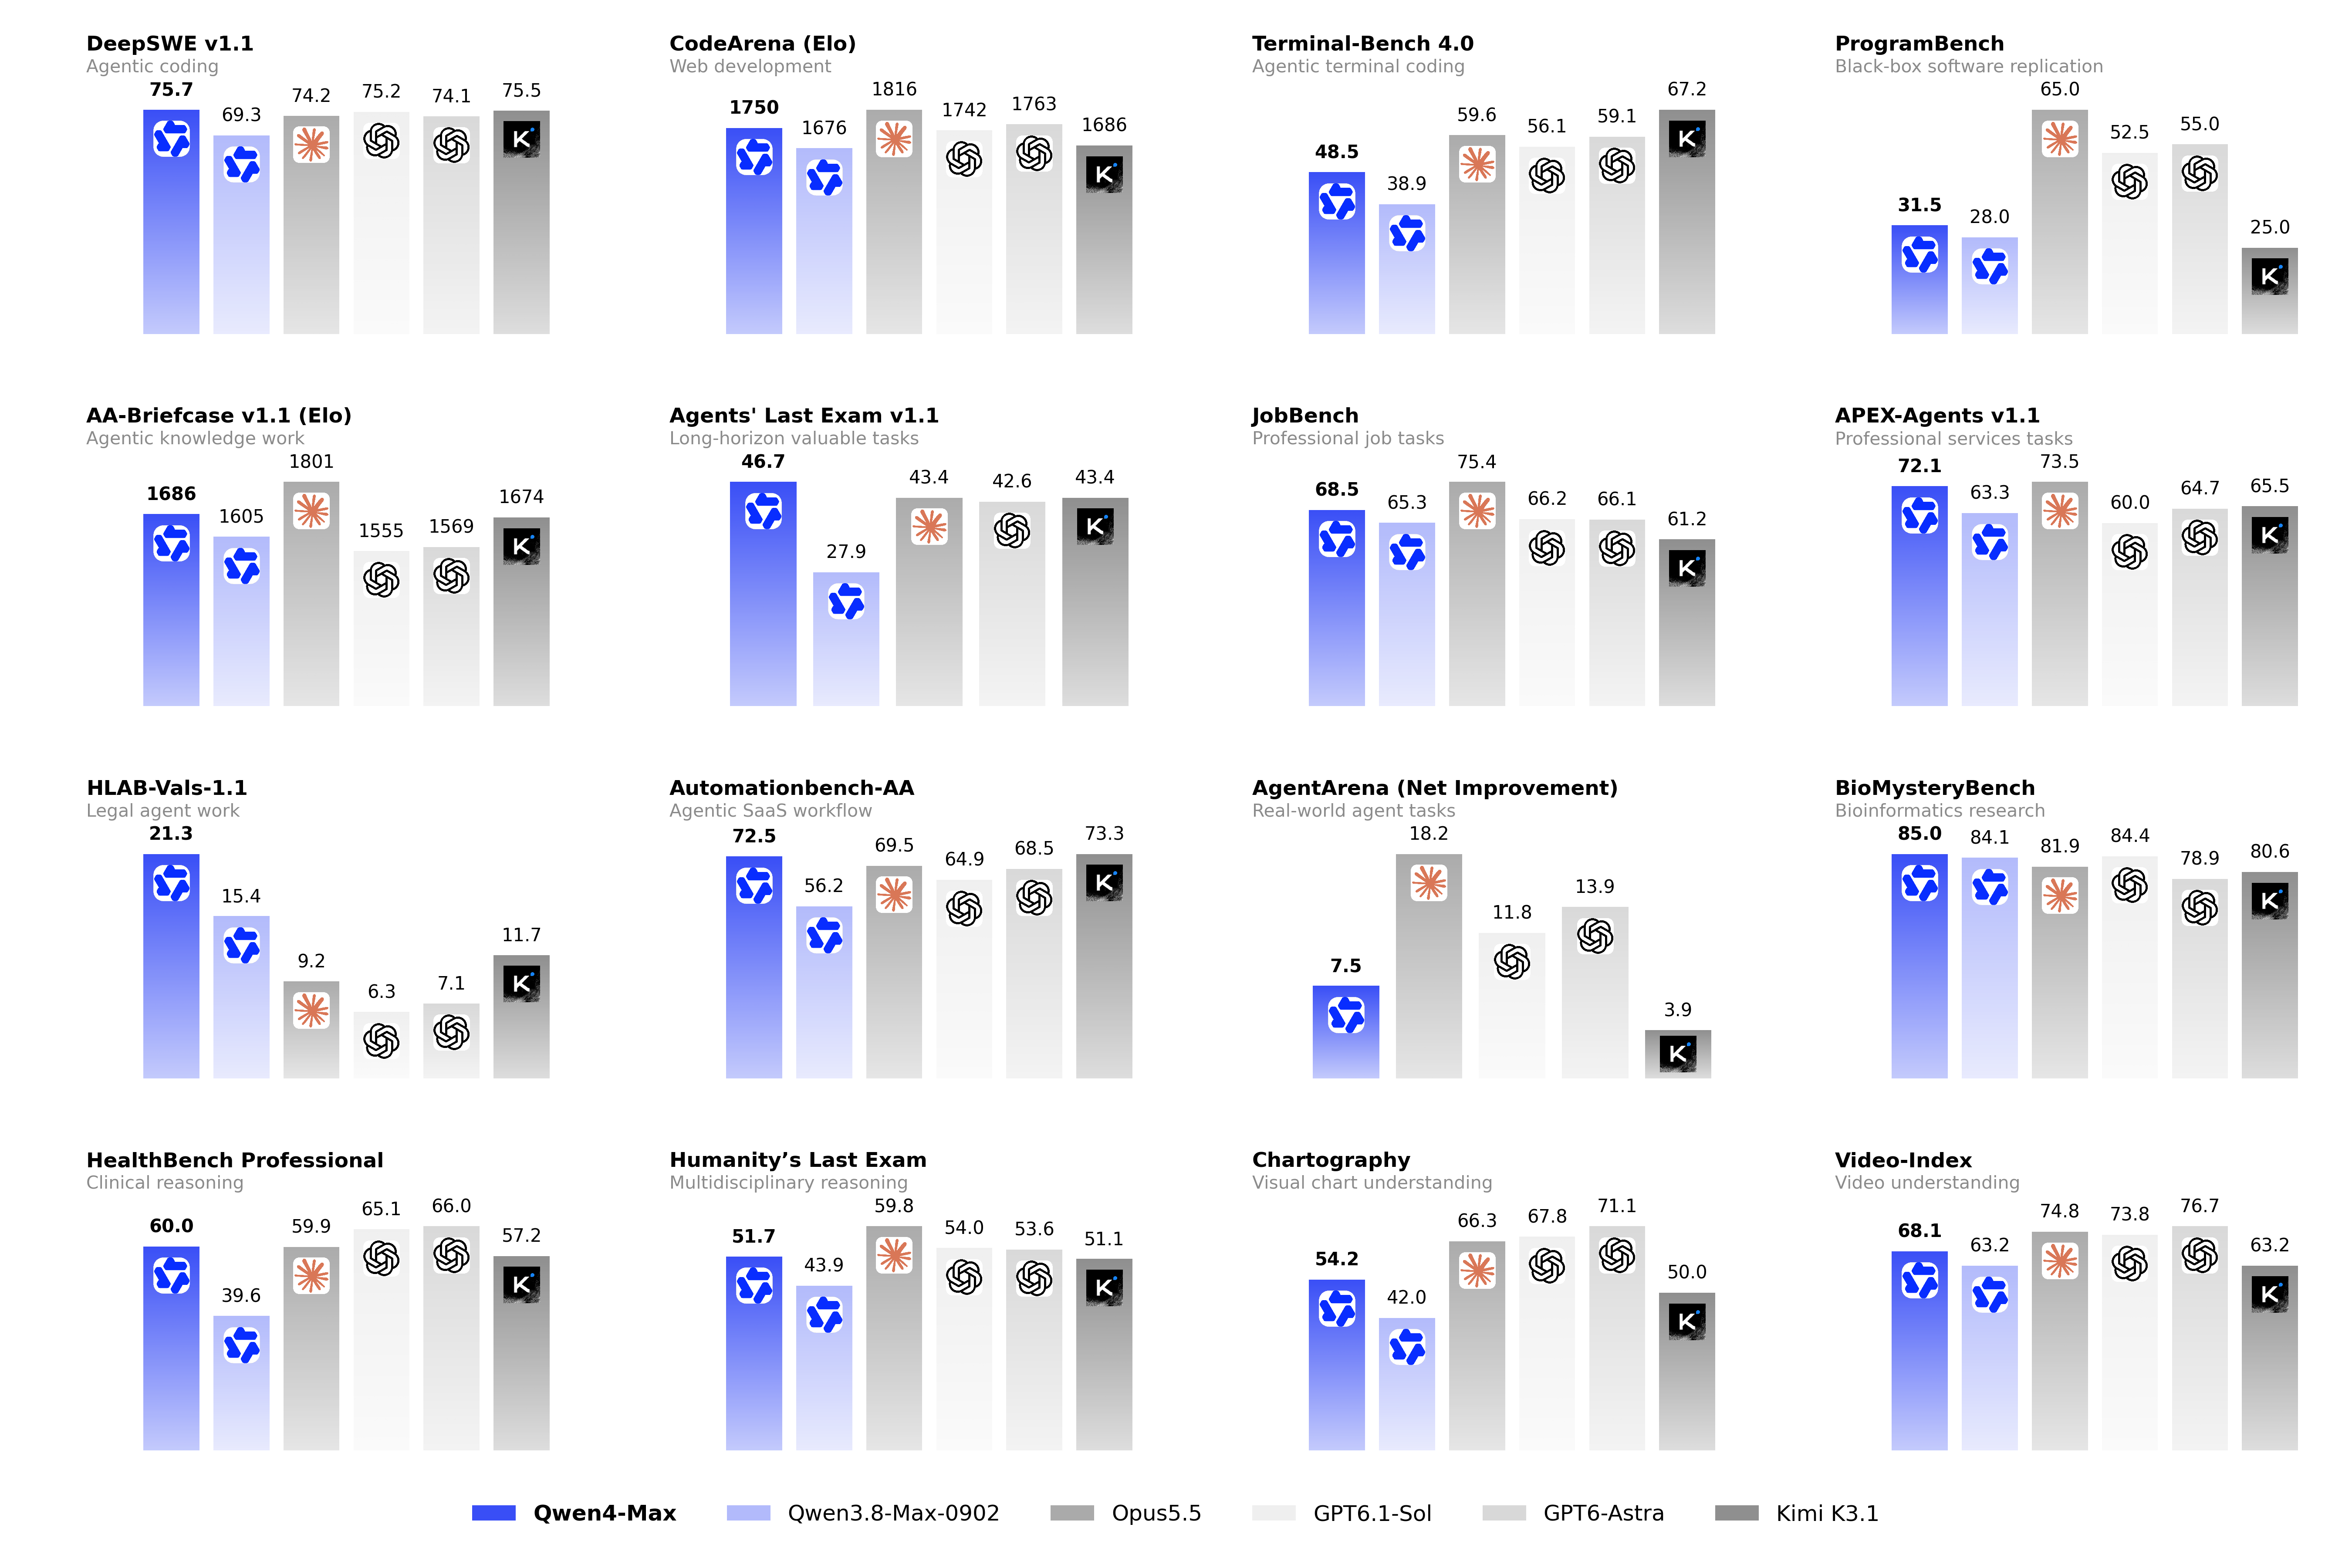
Launch results show gains over Qwen3.8 Max on Work360 and the Artificial Analysis Intelligence Index. Arena adds an early look at how long coding-agent runs can take. These figures were checked on November 17, 2026.
| Evaluation | Qwen4 Max result | Baseline or test setting |
|---|---|---|
| Alibaba Work360 | 35% fewer tokens at High reasoning effort and about 60% lower average cost per task | Alibaba’s own comparison with Qwen3.8 Max |
| Artificial Analysis Intelligence Index | Score of 43, with an average evaluation cost of $3.27 per task | Qwen3.8 Max (0902) scored 34 and averaged $10.02 per task on the index |
| Arena coding agents | Median of 30.1 minutes and $3.67 per task | Preliminary result at xHigh reasoning effort |
Alibaba’s Results for Professional and Agent Work
Work360 covers specialized professional tasks. Alibaba’s result gives teams a reason to retry workflows where Qwen3.8 Max spends several rounds reading tool output or revising a deliverable. The savings are specific to Work360. If Qwen3.8 Max is your baseline, the earlier Qwen 3.8 Max vs. Kimi K3 comparison offers context on its coding and long-context use cases.
Independent Reasoning and Coding Results
Across the Intelligence Index suite, Artificial Analysis recorded 127 million output tokens for Qwen4 Max and 150 million for the September Qwen3.8 Max snapshot. The newer model scored higher while generating fewer tokens on that suite. For coding, Arena’s preliminary xHigh result gives you a reason to measure elapsed time alongside cost. A job that can run overnight can tolerate a longer wait than a developer working through a fix interactively.
Qwen4 Max Pricing and How to Get Access
These are QwenCloud’s Singapore API list prices in US dollars per million tokens, checked on November 17, 2026.
| Token type | Qwen4 Max | Qwen3.8 Max |
|---|---|---|
| Uncached input | $1.50 | $2.00 |
| Output | $4.50 | $6.00 |
| Input served from the implicit cache | $0.075 | $0.25 |
For a request with 100,000 uncached input tokens and 10,000 billed output tokens, Qwen4 Max costs $0.195, versus $0.26 for Qwen3.8 Max at the same usage. Both amounts exclude tool fees. If Qwen4 Max needs a second attempt with the same usage and no cache hit, the total rises to $0.39. The billed output can include reasoning tokens even when the final answer is short.
You can try a prompt or visual input in Qwen Studio. For pay-as-you-go access through QwenCloud or Alibaba Cloud Model Studio, use qwen4-max. If your app already routes through OpenRouter, use qwen/qwen4-max and check the serving provider’s prices and supported inputs. When you estimate the cost of a full agent job, add up the usage from every request, including calls made after a tool returns and any retries.
Should You Switch to Qwen4 Max?
Start with a failure you can reproduce. On a coding job, that might be a fix that passes its targeted test but breaks another path through the same feature. In document review, it might be an extraction that misses a contradiction between two versions of a policy. If your current model already handles routine chat or clean extraction within your accuracy and latency targets, keep it on those jobs. MyClaw’s guide to the best AI models right now can help you pick a baseline for each type of work.
For a coding trial, choose three closed tickets with known fixes. For each ticket, start both models from a clean copy of the repository at the commit before the fix. Use the same ticket, permissions, tools, and time limit. A pass means the patch fixes the reported behavior, clears the relevant tests, and leaves unrelated files alone. Record the exact model ID, serving provider, and reasoning setting for each run. For a document trial, give both models the same files and require a page or section reference for every discrepancy they flag.
Compare passes, elapsed time, and how often someone had to step in. For a model with at least one pass, divide the cost of all its attempts by the number of accepted results. If the gains show up mainly on the hardest tickets, route those to Qwen4 Max first. If both models pass all three, let elapsed time and cost decide which one to keep for that work.
Pilot Qwen4 Max in an OpenClaw Workflow With MyClaw
MyClaw hosts private OpenClaw agents that can run scheduled jobs while your computer is off. A recurring report gives you a practical pilot because you can inspect the output before changing the model your main workflow uses.
- Choose a report you can check. In MyClaw, pick a report-only job such as summarizing failed CI checks. Save a baseline report from your current model. Require each report to name the failed check, cite the relevant log lines, and give a next step.
- Check access and run once. Follow the model setup in the Day 2 quick start. If your instance can use Qwen4 Max through OpenRouter, set the test agent to
openrouter/qwen/qwen4-max. Start a fresh session, confirm the active model, and check that the agent can read the logs. If the model is unavailable there, run a separate API trial with the same log files and record any differences in tools or inputs. - Schedule the report and review the results. After the hosted test agent passes a manual run, use the Day 6 automation guide to schedule its report and check that it reaches the right destination. Keep the acceptance checks fixed and track elapsed time, cost, and manual corrections across several runs.
Conclusion
Qwen4 Max is a strong candidate when Qwen3.8 Max regularly needs extra rounds to fix a bug, reconcile documents, or finish work that depends on several tools. Choose one recurring task and decide what counts as a pass before you run either model. Include failed attempts in the cost and record how much time someone spends checking or correcting the result. Move that task to Qwen4 Max if it meets your quality bar and cuts total cost or review time. Keep the current model available while you repeat the comparison on the next workflow.
Skip the Setup, Run Best-in-Class AI Agents Now
Launch a managed OpenClaw or Hermes Agent workspace in minutes, with always-on hosting, updates, and support handled by MyClaw.